The introduction of HBM4 architecture marks a fundamental pivot point in artificial intelligence infrastructure, breaking the persistent memory wall that has constrained extreme-scale compute. As hyperscalers scale multi-trillion-parameter frontier models, high-bandwidth memory design has transitioned from a standardized commodity to deeply customized silicon interconnects. This generational upgrade fundamentally shifts packaging standards, foundry partnerships, and advanced semiconductor packaging strategies for high-performance computing worldwide.
The Silicon Interconnect Breakthrough: Moving to a 2048-Bit Interface
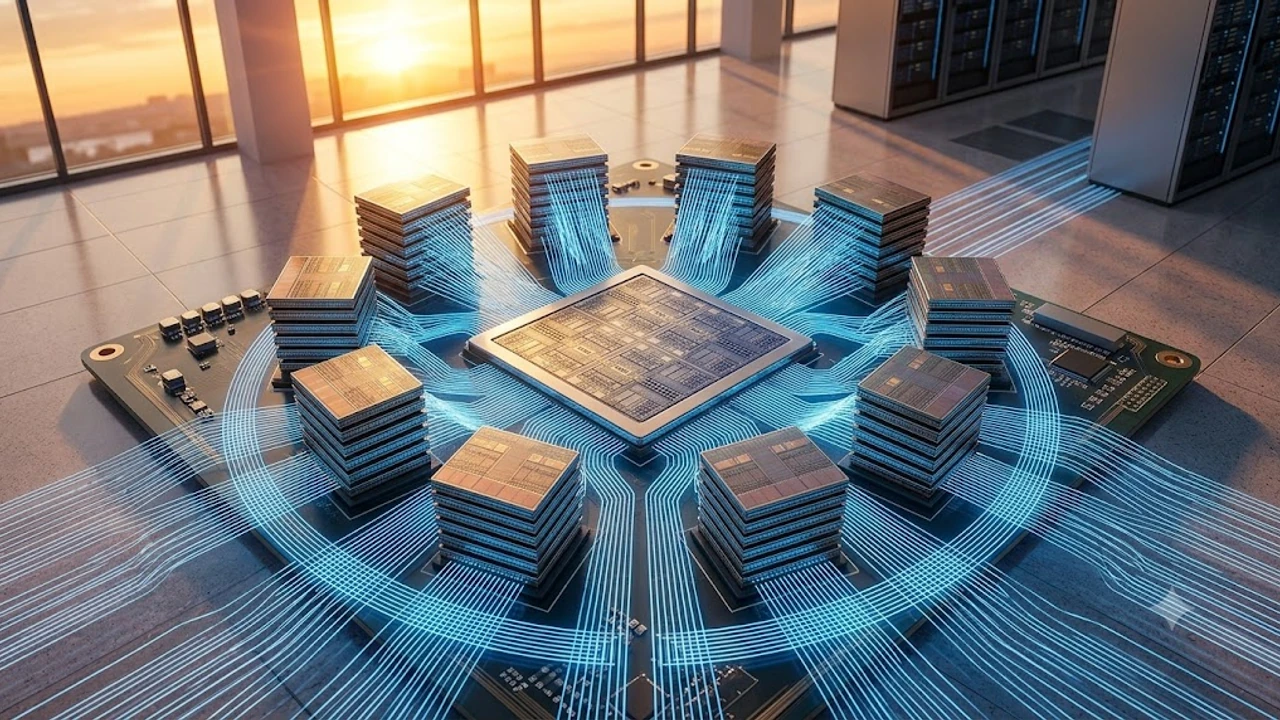
The jump from HBM3e to HBM4 represents the most radical physical interface redesign in memory history. For three generations, High Bandwidth Memory relied on a rigid 1024-bit interface per stack, scaling bandwidth almost exclusively by driving clock frequencies higher through signal integrity bottlenecks. HBM4 shatters this architectural ceiling by doubling the interface width.
Doubling the Bus Width to Solve Physical Interconnect Limits
By expanding the bus width to 2048 bits, HBM4 achieves over 1.5 TB/s to 2.0 TB/s per stack without requiring thermal-punishing I/O frequencies. Operating a wider bus at a moderate signaling rate circumvents the steep dynamic power penalties that plagued high-frequency HBM3e configurations.
- Physical Pin Density: Routing 2048 high-speed data lines requires microscopic micro-bump pitches dropping below 25 micrometers.
- Signal Integrity Preservation: Lower operating frequencies mitigate high-frequency cross-talk and insertion losses across the silicon interposer.
- Energy Efficiency Scaling: The architectural doubling cuts energy-per-bit consumption by approximately 30% compared to pushed-to-the-limit HBM3e lines running at 9.6 Gbps.
This interconnect density transforms board routing. Accelerators can now access immense aggregate bandwidth exceeding 10 TB/s across a single processor subsystem without triggering catastrophic local thermal runaway.
Thermal Dissipation and Through-Silicon Via Densities
Stacking 12 to 16 DRAM dies vertically generates unprecedented localized heat flux. In HBM4, the Through-Silicon Via (TSV) count doubles to accommodate the 2048-bit bus, turning the vertical interconnect grid into both an electrical pathway and a thermal conduit.
Precision thermal mapping by semiconductor consortia shows that TSVs conduct heat vertically through the silicon stack up to four times faster than standard epoxy mold compounds (EMC), transforming the internal interconnect lattice into a crucial passive heatsink.
Memory manufacturers utilize advanced micro-gap underfills and wafer-thinning techniques—reducing die thickness to under 30 micrometers—to ensure that the denser TSV field conducts heat outward into the integrated heat spreader (IHS) rather than trapping it within intermediate memory layers.
The Physics of Micro-Bump vs. Direct Copper Bonding
The transition to a 2048-bit bus forces an engineering reckoning at the interconnect layer:
- Micro-Bump Soldering: Traditional thermo-compression bonding with non-conductive film (TC-NCF) reaches its physical scaling wall around a 15-to-20 micrometer bump pitch due to solder bridging risks.
- Direct Copper-to-Copper Bonding: Hybrid bonding eliminates the micro-bump entirely, fusing copper pads embedded in dielectric materials at room temperature before thermal annealing.
- Z-Height Advantages: Eliminating bumps slashes stack height by up to 20%, fitting 16-high DRAM die configurations within the exact mechanical package envelopes specified for standard server racks.
The Base Die Foundry Revolution: The End of Memory In-House Isolation
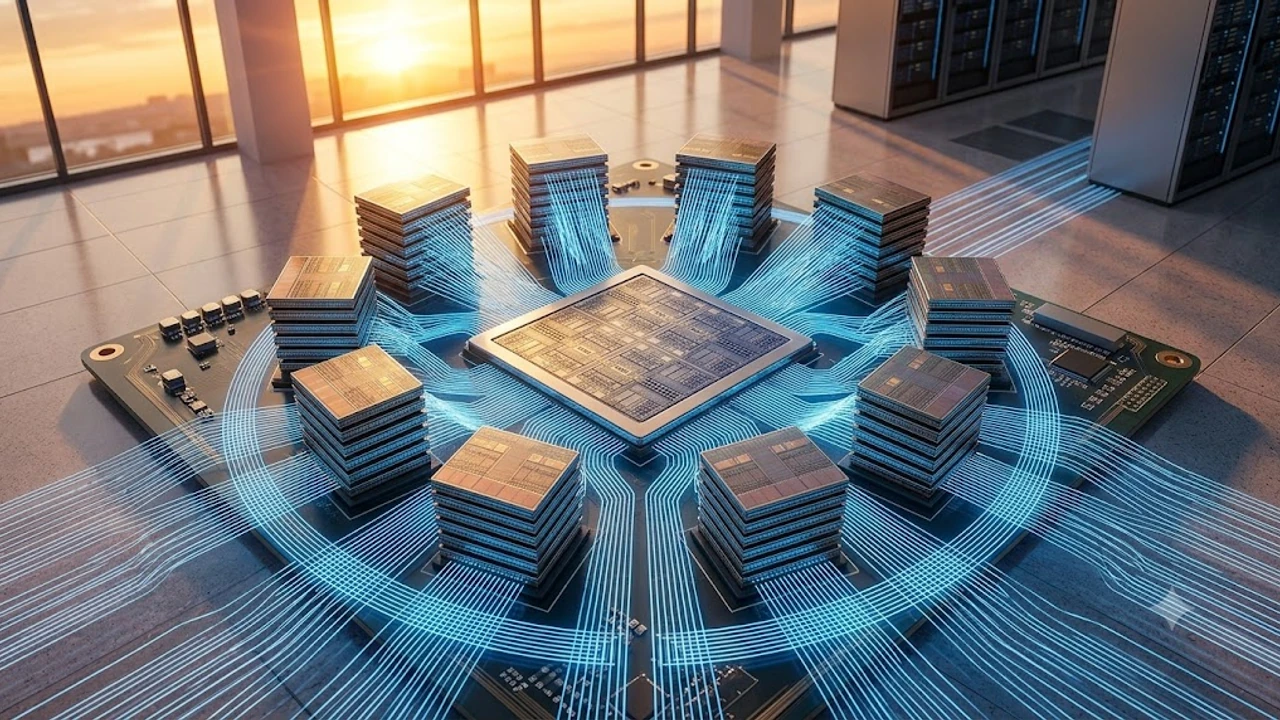
Historically, memory manufacturers produced the entire HBM stack internally, manufacturing the base (logic) die on mature, proprietary DRAM-like wafer processes. With HBM4, this model has ended. The base die must now handle complex routing for a 2048-bit interface, built-in self-test (BIST) routines, and custom logic functions, forcing DRAM vendors to outsource base die fabrication to pure-play advanced foundries.
Transition to Advanced Logic Nodes (4nm and 3nm)
The HBM4 base die is no longer a passive routing substrate. It is built directly on cutting-edge FinFET and nanosheet logic nodes (5nm, 4nm, and 3nm).
- Routing Density: The thousands of TSV landing pads and 2048 interconnect tracks demand multiple metal layers available only in premier logic processes.
- Power Delivery Networks: Sub-nanometer standard cells reduce voltage droop under sudden high-throughput load shifts during massive transformer attention computations.
- Die Area Optimization: Moving to advanced foundry nodes prevents the base die footprint from ballooning beyond the standard dimensions of the upper memory die stack.
This shift integrates high-performance memory directly into the mainstream logic cadence, closely aligning memory fabrication cycles with flagship processor nodes.
Co-Designing Custom Memory for Hyperscale Workloads
By moving the base die to advanced foundry processes, the memory subsystem becomes customizable. Cloud service providers and sovereign AI chip architects now embed custom IP blocks directly beneath the memory stack.
Custom base dies allow cloud vendors to insert domain-specific data decompression, near-memory filtering engines, and tailored cryptographic primitives directly on the memory stack floor, bypassing host processor bottlenecks entirely.
This integration mirrors larger hardware supply realignments analyzed in US Secondary Tariffs 2026: 3 Tech Supply Chain Impacts, where supply chain independence and specialized proprietary silicon increasingly dictate vendor survival. Custom base logic transforms standard memory stacks into active compute enablers tailored directly to private data center software stacks.
Architectural Impact on Frontier AI: The Battle Against the Memory Wall
Modern AI architectures—specifically large reasoning models, sparse mixture-of-experts (MoE), and massive context-window transformers—are fundamentally memory-bandwidth bound rather than compute bound. The teraflops available in modern GPU cores frequently sit idle waiting for weights and Key-Value (KV) cache tensors to arrive from memory.
Alleviating Latency in Mixture-of-Experts (MoE) Routing
Mixture-of-Experts architectures activate only a fraction of their total parameters per token. While this reduces theoretical compute operations, it dramatically increases memory bandwidth pressure:
| Architecture Metric | HBM3e Memory Subsystem | HBM4 Advanced Subsystem | Operational Impact |
|---|---|---|---|
| Bus Width per Stack | 1024-bit | 2048-bit | $2\times$ raw pin concurrency |
| Maximum Stack Capacity | 24GB – 36GB (8H/12H) | 48GB – 64GB (16H Hybrid Bonded) | Eliminates off-package parameter spillover |
| Per-Stack Bandwidth | ~1.18 TB/s | >2.0 TB/s | Eliminates sparse gating latency stalls |
| I/O Energy Efficiency | Base baseline (~5-7 pJ/bit) | Optimized (~3.5-4.5 pJ/bit) | Preserves thermal budget for compute silicon |
When an MoE network routes tokens to disparate experts spread across different physical memory locations, HBM4’s doubled bus width and lower latency enable instant weight fetches. Tokens complete their forward pass without stalling compute execution units.
Enabling Real-Time Infinite Context Processing
Long-context inference demands staggering amounts of volatile memory purely to store the Key-Value (KV) cache. A 1-million-token context window can demand hundreds of gigabytes of working memory per active user session.
- Stack Capacity Scaling: HBM4’s 16-high stacking enables 48GB and 64GB stacks, delivering up to 512GB of coherent, unified ultra-fast memory on an eight-stack single-accelerator board.
- Attention Kernel Throughput: Matrix multiplication kernels pull KV cache data at multi-terabyte-per-second rates, maintaining interactive generation speeds even with multi-million-token inputs.
- De-quantization Speed: High-bandwidth throughput allows real-time de-quantization of 4-bit weights into higher-precision FP8 or FP16 registers on the fly without introducing latency bubbles.
This capability bridges enterprise computing with on-device advances like those explored in Why IFA 2026 Shifted to On-Device AI: 3 Key Takeaways, showing how memory scale dictates the boundaries of real-time machine intelligence across both data centers and edge infrastructure.
Supply Chain Shifts: The Tri-Party Co-Opetition of Memory, Foundry, and Packaging
The deployment of HBM4 shatters the historical demarcation lines separating pure-play memory makers, third-party foundries, and outsourced semiconductor assembly and test (OSAT) vendors. Building a functional HBM4-accelerator package now demands unprecedented, highly synchronized coordination among three historically separate industries.
The SK Hynix, TSMC, and Samsung Ecosystem Dynamics
The commercial race centers on tight industrial ecosystems. SK Hynix has partnered directly with TSMC to fabricate base dies on TSMC’s 5nm/3nm process nodes while integrating the completed stacks via CoWoS-L packaging.